Cover Story — October 2026

Cactus Whistle: 17 MB Speech-to-Text, Tested in French

Dominic Plouffe · Oct 12, 2026 · 6 min read

I ran Cactus Whistle, a 16.9 MB open speech-to-text model, on Québec French, accented English and noise. Here is what it got wrong.

Read the full story →
01

MXC Sandbox: Where Your Agent’s Code Should Run

AI Security · 7 min · Oct 12, 2026
03

Codebase Port Cost: What ts-rust Really Took

Infra · 6 min · Oct 9, 2026

Latest

Today
Infra

LiteLLM Budget Limits: max_budget Needs Postgres

A LiteLLM budget cap does nothing without a database. I tested v1.104.0, then set up per-agent keys and a team spend limit in ten minutes.
Dominic Plouffe · 7 min Oct 7, 2026
Open Source

Vectorless RAG: Reasoning Over a Tree, Not Cosine Search
Vectorless RAG swaps embeddings for a table-of-contents tree the LLM walks. What PageIndex does well, what a query costs, and who should…

Dominic Plouffe · 6 min
Open Source

MoE Expert Offloading: 125B on a 12GB GPU, With Catches
MoE expert offloading lets a 12GB GPU run a 125B model, but only for one user at a time. What Strata's numbers…

Dominic Plouffe · 6 min Oct 6, 2026
Agentic AI

Why I’m Betting on a Minimal Agent Harness
Pi 1.0's own release notes claim a 40% prompt-token cut from Codemode. Here's the arithmetic I'd run before trusting a minimal agent…

Dominic Plouffe · 6 min Oct 5, 2026
Agentic AI

Open-weight decision models: Clef vs Strands Decider
Clef and Strands Decider 2B are open-weight decision models that return a calibrated score, not text. Here's what shipped and why it…

Dominic Plouffe · 6 min Oct 4, 2026
AI Marketing

The Hidden Risk of Letting AI Manage Ad Campaigns
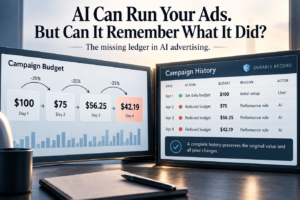
MCP's own specs disagree on whether it is stateful. Neither defines a record of what changed in your ad account — and…

Dominic Plouffe · 17 min Sep 5, 2026

Analysis

04

Your Agent A/B Test Was Broken Before You Ran It

Evals · Dominic Plouffe · 6 min · Sep 4, 2026
05

Half My Agent’s Budget Goes to Checking Its Own Work

Evals · Dominic Plouffe · 5 min ·
06

I Rewrote the Test Until My Writing Passed It

Evals · Dominic Plouffe · 5 min ·
07

The Bug Was Reproducible. My Logs Weren’t.

Agentic AI · Dominic Plouffe · 5 min ·
08

Credential Scanners Are Wearing Crawler Costumes

Security · Dominic Plouffe · 7 min · Aug 14, 2026
09

Crawled, Indexed, or Cited: How to Read AI Traffic in Your Server Logs

Data Analytics · Dominic Plouffe · 10 min · Aug 10, 2026
10

I Tried to Replace a Startup Team With Three AI Agents. Here’s What Happened in Week One.

Startup Agents · Dominic Plouffe · 17 min · Aug 8, 2026
11

A scheduled task is not a returning user

Uncategorized · Dominic Plouffe · 5 min · Aug 5, 2026