I sent five requests through LiteLLM v1.104.0 with max_budget set to $0.000001 and a mock model priced at one cent a token. Five answers came back, all HTTP 200, and the proxy was perfectly happy about it. A LiteLLM budget without a database behind it is a decoration, and the docs say so, but you have to be reading the right paragraph.
I care because of how Trellis uses LLMs. Our agents read Amazon seller catalogue data, and a catalogue is the kind of input where one bad loop turns into thousands of calls before anyone looks at a dashboard. Mettons a retry loop fires 10 calls a second at five cents each. That is $14,400 over an eight-hour night, and I made up the price but not the shape of the problem. The place to stop it is the gateway, not the provider’s billing page after the fact, and I already learned in my post about where an agent pipeline’s API bill went that the bill never lands where you expect.
Does a LiteLLM budget work without a database?
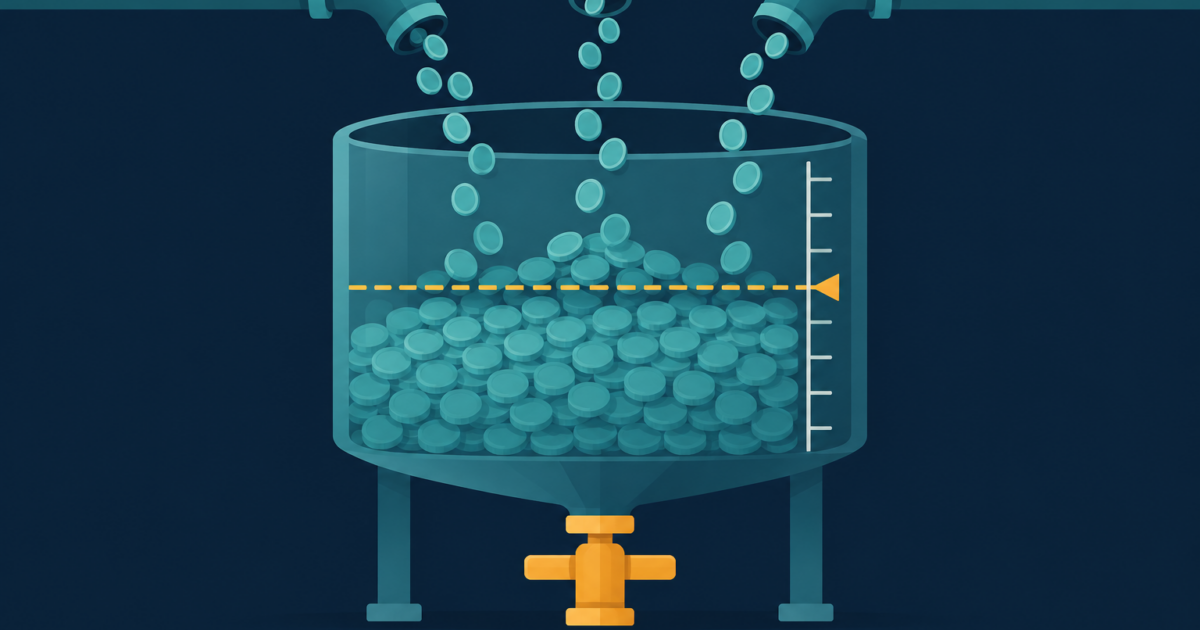
No. The budgets page in the LiteLLM docs is blunt about it: every budget “is enforced against spend read from the database, so none of them cap anything on a DB-less deployment.” The global max_budget in litellm_settings “fails open”, because the proxy only loads global spend when a database client exists, and with nothing to compare against the check is skipped.
The docs were my claim to repeat, so I went and checked it. I installed litellm[proxy]==1.104.0 in a clean virtualenv, pointed a model at a mock_response so no provider was involved, and set max_budget: 0.000001 with budget_duration: 30d. Then I hit /chat/completions five times. Five 200s.
Two details from that run. At startup the proxy printed one warning, and only one: a proxy-wide budget “is configured but no database is connected, so the budget will NOT be enforced and requests will never be blocked.” And when I tried /key/generate, it returned a 500 saying “DB not connected” and told me to set DATABASE_URL. So virtual keys fail loudly, while the global budget fails quietly. You add the budget line, you see a clean boot, you move on.
I did not test the Postgres side this week, because there is no Postgres in my sandbox. Everything about enforcement with a database below comes from the docs and the release notes, and I will say so each time.
v1.104.0 will not boot with sk-1234
The release that made me look is v1.104.0, published October 3. The change that matters is PR #42019: the proxy now refuses to start on an unset, empty or publicly known master key. The PR description explains the old behaviour. Copy the quick start, run with sk-1234, and anyone who can reach the port is a proxy admin who can create keys, read spend and change models. With no master key at all, everyone gets in.
I tested that one too. Same config, LITELLM_MASTER_KEY=sk-1234, and the proxy printed “refused to start: the master key is a publicly known default”, plus a openssl rand -hex one-liner to make a real key. The escape hatch is LITELLM_DANGEROUSLY_PERMIT_WEAK_OR_UNSET_MASTER_KEY=true, which the notes say is for local development.
Why does this belong in a budget post? Because a budget you can raise with a public password is not a budget. The master key is the thing that edits every other limit. If a staging box won’t come up after the upgrade, this is why, and the error says an exported variable wins over .env, which would have cost me twenty minutes of staring.
Setting up a LiteLLM budget per agent in ten minutes
Here is the shape I would use. Postgres first, because nothing else works without it. Pin the image: ghcr.io/berriai/litellm:v1.104.0, since v1.105.0-rc.1 is already around and a gateway that sits in front of your bills should not move under you.
export LITELLM_MASTER_KEY="sk-$(openssl rand -hex 32)"
export DATABASE_URL="postgresql://user:pass@host:5432/litellm"
Then one team, with its own money and its own reset. The field names below come from the docs’ own curl examples:
curl 'http://localhost:4000/team/new' \
  -H "Authorization: Bearer $LITELLM_MASTER_KEY" \
  -H 'Content-Type: application/json' \
  -d '{"team_alias": "catalogue-agents", "max_budget": 50, "budget_duration": "30d"}'
Then one virtual key per agent, drawing on that team, each with a smaller cap of its own:
curl 'http://localhost:4000/key/generate' \
  -H "Authorization: Bearer $LITELLM_MASTER_KEY" \
  -H 'Content-Type: application/json' \
  -d '{"team_id": "", "key_alias": "listing-rewriter", "max_budget": 10, "budget_duration": "7d"}'
Each agent gets its own key and never sees the master key. When the rewriter loops, it hits its $10 and gets a budget error back, and the other agents keep working. The docs show the failing call returning an ExceededBudget error, which is the thing you want to see on purpose, once, before you trust any of this. Set a $0.01 key, call it three times, watch it refuse.
Two reset details I would have missed. The proxy checks for budget resets every 10 minutes by default, to save database calls, so a “30s” duration in the docs examples does not mean thirty seconds in real life. And if a key belongs to a team, only the team and team-member budgets apply. The key owner’s personal budget is ignored.
Four ways a LiteLLM budget still leaks
Even with Postgres, the docs list four leaks.
Free models skip the check. If a model has input_cost_per_token: 0 and output_cost_per_token: 0 set explicitly, budget checks are skipped entirely for it. That is deliberate, so exhausted keys can fall back to a local Ollama model. It also means a typo in a price field is a hole.
Concurrent requests are the second. Budget reservation is on by default: LiteLLM estimates the worst-case cost from max_tokens (or the model limit) and holds it against the budget before the provider sees the request. So set max_tokens, otherwise the estimate falls back to the model’s configured limits, which is a big number for a small key.
Third, Redis. Spend checks read a counter in Redis, and the docs admit that if Redis restarts from an old snapshot the counter can be lower than the real spend, so a key can run past its cap until it corrects. The fix they give is general_settings: fail_closed_budget_enforcement: true, which validates against the database on every budgeted request. I would turn it on and pay the latency.
Fourth, batches. A POST /batches carries a file id, not prompts, so LiteLLM cannot price the job at submission. The cost is recorded when the batch completes. A batch can walk past a budget and you only learn afterwards.
What is open source and what is not
LiteLLM is “mostly MIT with an enterprise folder”, and I am using the repo’s own LICENSE file as the source: everything outside the enterprise/ directory is MIT, and that directory has its own license. GitHub’s licence field says NOASSERTION for exactly that reason.
For budgets, the practical line is in the docs. Keys, teams, team members, global budgets and budget_duration are plain proxy features. Budgets per model on a key (model_max_budget), including the “$200 a month on Opus per engineer” scope, carry a banner saying they need an Enterprise license, and so does key rotation. “Project Management” is tagged beta in the sidebar. I would build on the first group and treat the second as a paid line item you probably do not need yet.
Who should do this
If you have more than one agent, or more than one person with an API key, put a gateway with a budget in front of them this week. Me, I’d rather find out a cap works by hitting it with a one-cent key on a Tuesday afternoon than by reading an invoice.
If you run one script on your laptop, skip all this and set a hard limit in the provider dashboard.
The part I have not measured is how much the Redis counter drifts under real load. Next week I will run the Postgres version with a $0.01 key and a few hundred concurrent calls, and write down how far past the cap it lands.